

Introduction: Why Data Sovereignty Matters Now
In 2025, the battle for data ownership has evolved beyond academic discussions to become an urgent economic and personal reality for millions. As AI systems ingest vast amounts of information to power everything from content creation to healthcare diagnostics, a fundamental question has emerged: Who truly owns and controls the data that fuels this revolution?
This question isn't merely philosophical—it has profound implications for economic fairness, personal privacy, and the distribution of power in our digital society. Recent data shows major tech companies actively licensing content for AI training, with OpenAI's deal with News Corp valued at over $250 million and companies paying content creators $1-4 per minute for quality video footage. Meanwhile, both professional creators and ordinary individuals seek similar control over how their digital footprints are used.
The data sovereignty movement represents a paradigm shift: from passive data subjects to active data stewards, from exploitation to compensation, and from opacity to transparency. This transformation is happening through three interconnected systems that together form the foundation of a more equitable digital future.
Three-Pillar Framework: Emerging Protection Ecosystems
Content Tracking & Monetization Infrastructure
The first pillar addresses how creative works are identified, tracked, and monetized in an AI-powered world:
Real-time monitoring technologies now track how creative works appear in AI training datasets. For example, Getty Images has deployed image recognition systems that can identify when their licensed photos are used to train generative AI models, enabling them to negotiate fair compensation.
Digital fingerprinting systems can identify when original content appears in AI outputs. The Content Authenticity Initiative, supported by Adobe, has developed tools that embed invisible markers in creative works, allowing creators to prove ownership when their style or content is mimicked by AI systems.
Diverse licensing models have emerged, including:
Direct licensing arrangements (like the Financial Times' deal with OpenAI)
Training fees based on content volume and quality
Revenue-sharing programs that compensate creators when AI-generated works derived from their content generate value
Content licensing deals are becoming standard practice across media companies, with organizations like Axel Springer, News Corp, and The Associated Press establishing precedents for how journalism and media content should be valued in AI training.
Personal Data Management Systems
The second pillar focuses on how individuals can control their personal information:
Tim Berners-Lee's Solid project is creating personal data "pods" that keep information independent from applications. These pods allow individuals to store their data on servers they choose while selectively granting access to services, effectively decoupling data storage from service provision.
Personal data stores (PDS) provide more transparent control over individual information. Platforms like Digi.me and Dataswift enable users to aggregate their personal data from various sources and selectively share it based on clear terms and potential benefits.
EU's Data Act, set to take effect in September 2025, establishes new standards for data flows between businesses and consumers, requiring companies to make data portable and accessible to the individuals who generate it.
Enhanced control technologies including:
Differential privacy techniques that allow individuals to contribute data to valuable analyses while maintaining mathematical guarantees about their privacy
Homomorphic encryption enabling computations on encrypted data without decryption, allowing AI systems to learn from personal data without directly accessing it
Regulatory & Ethical Frameworks
The third pillar encompasses the legal and normative structures supporting data sovereignty:
State privacy laws taking effect in early 2025 include:
Delaware, Iowa, Nebraska, and New Hampshire laws becoming active on January 1, 2025
New Jersey's comprehensive privacy law following on January 15, 2025
Each establishing stronger consent requirements for data collection and processing
Neural privacy is emerging as a regulatory focus for brain-computer interfaces, with the Neurorights Foundation successfully advocating for protections against unconsented access to neural data in three countries so far.
Growing regulation of data brokers through judicial privacy laws now requires greater transparency about what personal information is collected and sold, with the FTC implementing new rules requiring explicit consent for sensitive data transfers.
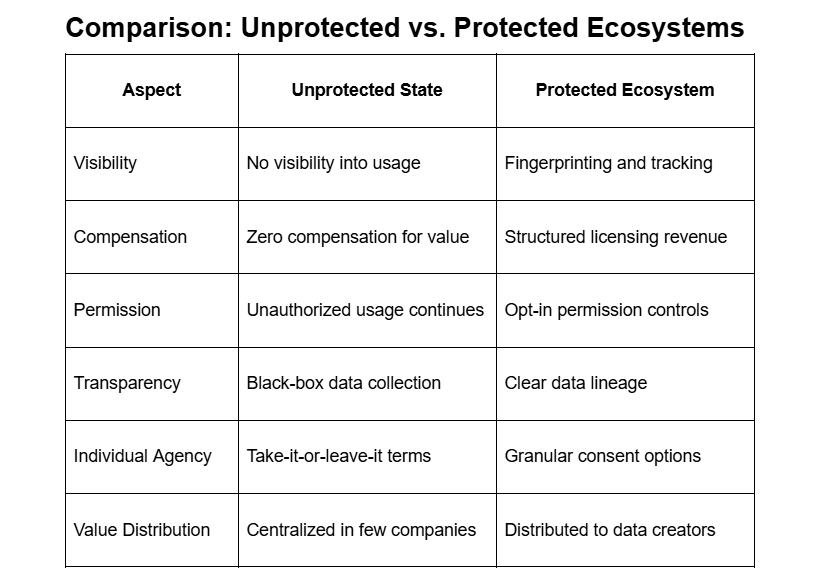
Comparison: Unprotected vs. Protected Ecosystems
Implementation Advancements & Remaining Challenges
Content licensing for AI is rapidly evolving, with over two dozen content owner deals publicly confirmed as of late 2024. The Journalistic Content Licensing Coalition (JCLC) has established standardized terms that make it easier for smaller publishers to participate in these arrangements. Similarly, Creative Commons has launched an "AI-Training Rights" designation that allows creators to specifically address how their work can be used by machine learning systems.
However, these arrangements primarily benefit larger institutions and media companies rather than individual citizens. A photographer whose images were used to train popular image generation models might receive no compensation, while Getty Images negotiates multi-million dollar licensing agreements for similar content.
Personal data sovereignty tools remain in earlier stages, with emerging standards and technologies that haven't yet reached widespread implementation. The average consumer faces significant hurdles in understanding, accessing, and controlling their data across dozens of services. Companies like Apple have begun to address this through features like App Privacy Reports and Data & Privacy tools, but truly comprehensive personal data management remains elusive for most.
A key concern in 2025 is that as companies collect "data exhaust" - the trail of information generated simply by existing in the modern world - the value often remains concentrated in corporate platforms rather than benefiting the individuals generating the data. Your location history, browsing patterns, and interaction data create billions in value for tech platforms, but individuals have limited mechanisms to participate in this value creation.
How Individuals Can Assert Control Today
While comprehensive data sovereignty remains a work in progress, everyday citizens can take several concrete steps now:
Audit your digital footprint using tools like Privacy Badger and Blacklight to understand what data is being collected
Request your data through GDPR/CCPA access rights from major platforms and review what's being stored
Use personal data stores like Digi.me to begin centralizing and controlling access to your information
Support data cooperative initiatives like Driver's Seat Cooperative that enable collective bargaining for data creators
Choose services with data dignity features that provide transparency and control over how your information is used
Strategic Implications
The emergence of these protection systems signals three transformative shifts:
Movement from reactive complaints to proactive licensing models - Instead of after-the-fact lawsuits, we're seeing the development of systems that establish rights and compensation before data usage begins
Evolution from individual vulnerability to structured control mechanisms - The power dynamic is slowly shifting from unilateral corporate control to more balanced negotiations between data creators and data users
Recognition that, as Wipfli notes, "the next wave of tech fortunes won't be made by those who collect the most data, but by those who determine who truly owns it"
The future of our digital economy appears increasingly tied to these sovereignty systems. As AI becomes even more pervasive, the infrastructure determining who controls data—and who benefits from it—will be as important as the technology itself.
Conclusion: Toward a More Equitable Data Future
The central question isn't about stopping AI development, but ensuring fair treatment through fundamental rights of consent, compensation, and fair competition. With continued development of both content licensing models and personal data sovereignty tools, the path toward more equitable data control is becoming visible but still requires substantial advancement.
This data sovereignty revolution represents a crucial rebalancing of power in digital spaces. For content creators, it means fair compensation for their contributions to AI advancement. For everyday citizens, it promises greater control over their digital lives and the opportunity to share in the value their data creates.
The companies and platforms that embrace these changes—rather than resist them—will likely find themselves better positioned for the next phase of the digital economy: one where trust, transparency, and fair value exchange become competitive advantages in an increasingly data-conscious world.